Featured
FrontierMath
Podcast
Jan. 29, 2026
FrontierMath
Few domains test AI reasoning as clearly as mathematics, where answers can be verified automatically and the hardest problems extend to the frontier of human knowledge. Epoch tracks how AI is performing on mathematical tasks over time, including through FrontierMath, our own benchmark of expert-level problems designed to test the limits of what today's best systems can do.
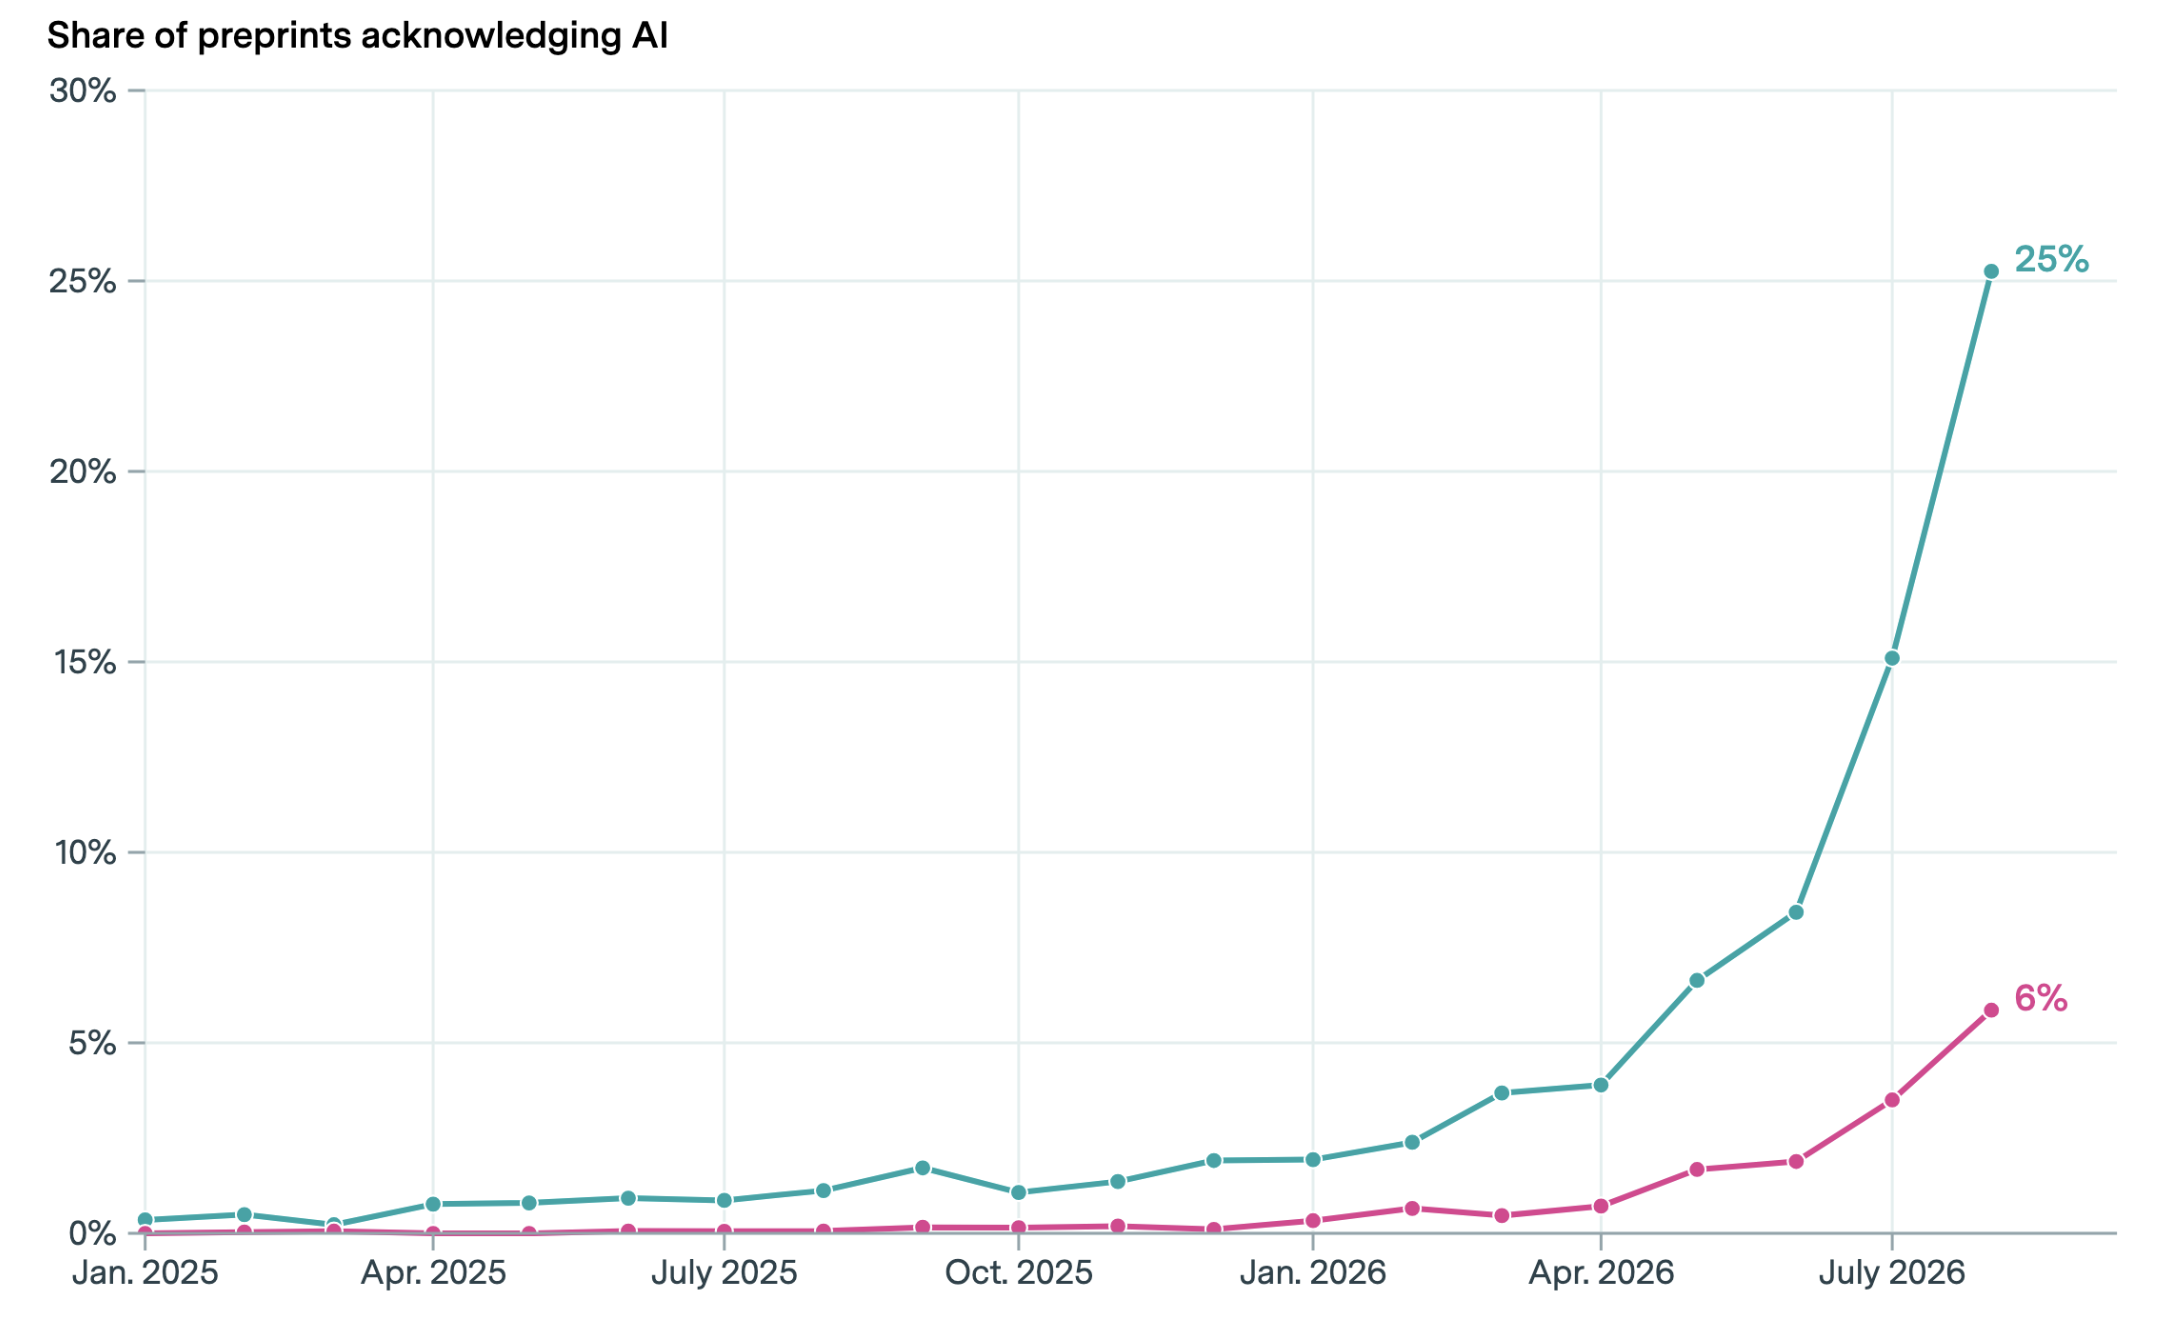
Acknowledgments of AI use in arXiv math preprints rose from 4% in April 2026 to 25% in August, with 6% crediting AI with a substantial research contribution.
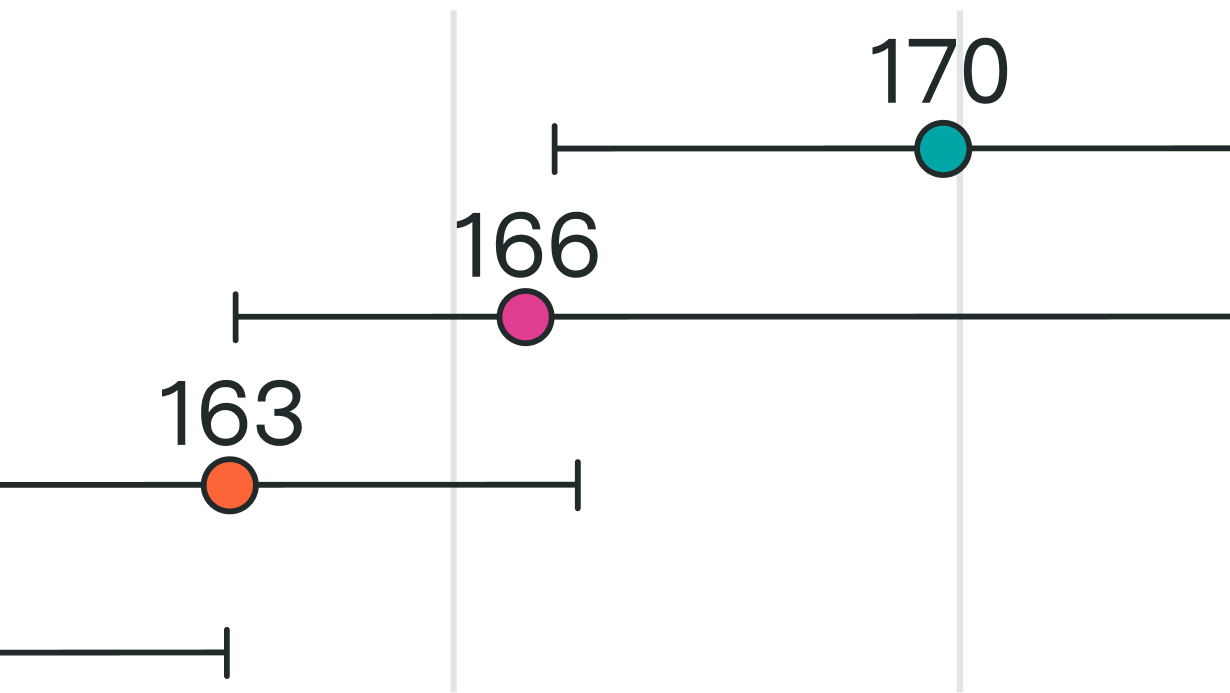
OpenAI's GPT-6 Astra tops the Epoch Capabilities Index (ECI) with a score of 166, ahead of Claude Fable 5.1 at 164 and GPT-5.6 Sol at 162. Its Math-ECI of 170 sets a new record, but on software engineering benchmarks its SWE-ECI of 164 still lags behind Fable 5.1's 167.
A benchmark of 68 significant Erdős problems, open as of August 2026, curated by Thomas Bloom and formalized in Lean. AI systems must prove or disprove them within a fixed budget.
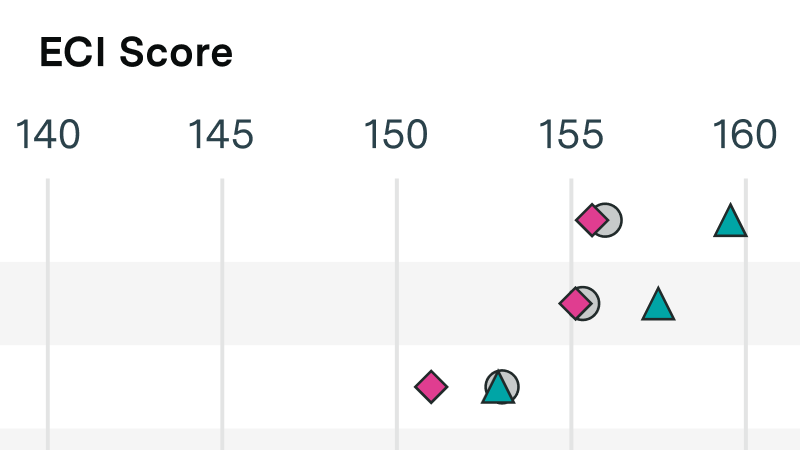
Relative to their general Epoch Capabilities Index (ECI) values, Anthropic’s Claude models overperform on software engineering benchmarks (aggregated by the SWE-ECI) and underperform on math (Math-ECI). The SWE overperformance has been consistent across most generations, and remains in recent models. The math gap may be narrowing — Opus 4.6 and 4.7 both have Math-ECIs within 1 point of their general ECI, compared to larger gaps for earlier models.
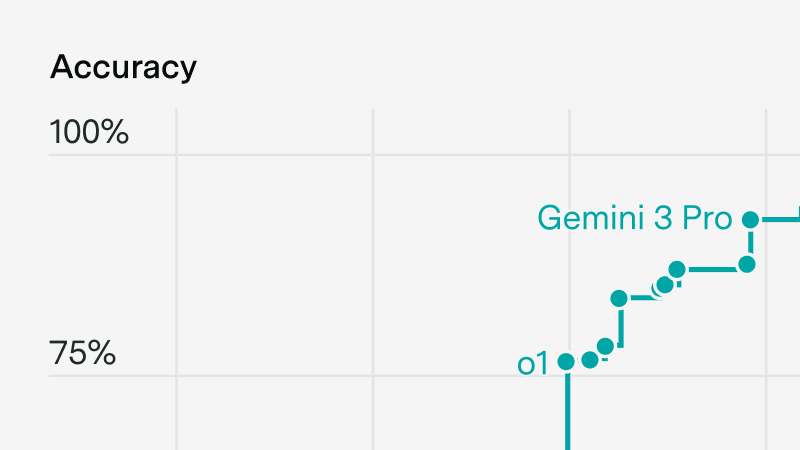
Give up at least one of: text only, short time horizon, easy to grade, and expert human superiority.
In this episode, Greg Burnham and Tom Adamczewski join Anson Ho to push back on benchmark pessimism and dig into what the next generation of AI benchmarks could look like.
In this episode, Daniel Litt chats with the hosts about AI’s limits in mathematics, accelerating math research, and how to measure progress on open problems.
Benchmarking AI on a collection of unsolved mathematics problems that have resisted serious attempts by professional mathematicians.
57% of problems have been solved at least once.
Improved use of knowledge and precision, helpful for research, more conceptual in geometry, but limited creativity and citation issues.